Text to Speech in the Modern Workplace: How AI Voice Technology Is Reshaping Business Communication
Published: September 28, 2026
Enterprise software has spent the last decade digitizing paperwork, but a quieter shift is happening in parallel: written content is increasingly being converted into spoken audio. From compliance training modules to customer support scripts, Text to Speech is moving from a niche accessibility feature into a standard layer of business communication infrastructure.
Text-to-speech (TTS) is the process of converting written text into spoken audio using AI algorithms trained on large volumes of human speech. Early implementations were limited to flat, robotic narration suitable mainly for accessibility tools. Today's voice synthesis technology can render pacing, emotion, and pronunciation with a level of nuance that makes automated narration usable in customer-facing contexts, not just internal accessibility use cases.
For operations and IT leaders, the appeal is straightforward: audio content can be generated at scale without hiring voice talent for every script revision, and it can be regenerated instantly when source documents change.
The numbers support the shift. According to Grand View Research's AI Voice Generators Market Report, the global market was valued at $3.6 billion in 2023 and is projected to reach $21.8 billion by 2030, growing at a CAGR of roughly 29.5%. That growth is being driven less by novelty and more by concrete use cases: e-learning platforms, IVR systems, audiobook production, and localization workflows that would otherwise require separate voice actors for every target language.
AI voice technology can automate how written content is delivered, while intelligent document processing can automate how business information is captured and used. docAlpha transforms incoming documents into structured, validated data for downstream business processes.
Extend the productivity benefits of AI from content delivery to everyday document-driven operations.
The biggest driver behind adoption is quality. Neural TTS models replaced older concatenative and formant-based systems, and the difference in output is substantial. Modern systems can clone a reference voice from a short audio sample, apply inline emotional cues, and generate cross-lingual output, meaning a voice recorded in one language can narrate content in another without re-recording.
Text to Speech platforms built on these newer architectures increasingly compete on naturalness benchmarks rather than raw feature lists, which has made independent evaluation more relevant for buyers than marketing copy.
Recommended reading: Discover How Document Automation Connects Content With Business Workflows
Not all platforms perform equally, and the differences matter once volume scales past a handful of scripts. Buyers evaluating an AI voice generator for production use should weigh naturalness (how convincingly the output passes as human), emotional controllability (whether pacing and tone can be adjusted without re-prompting from scratch), language coverage, and API pricing per character, since costs compound quickly at enterprise volume.
Fish Audio is one example of how these criteria are being addressed in practice. Its S2.1 Pro model reports leading results on independent benchmarks such as the Audio Turing Test and EmergentTTS-Eval, supports voice cloning from roughly 15 seconds of reference audio, and applies inline emotion tags (for instance, indicating a whisper or an excited tone) directly within the text rather than through separate parameter settings. It also supports cross-lingual generation across 80+ languages, with API pricing publicly listed at roughly $15 per million characters. The underlying model is available under an open-weights license, though commercial deployment requires a separate paid license, a distinction worth confirming during procurement.
Text-to-speech demonstrates how AI can transform familiar business content into something more accessible and useful. docAlpha applies AI-powered intelligent document processing to another critical challenge - turning business documents into validated data for automated workflows.
Move AI beyond isolated capabilities and use it to improve the processes employees rely on every day.
Text to Speech adoption is not without friction. Voice quality still varies meaningfully between vendors, and buyers should test with their own scripts rather than relying on demo audio. Commercial licensing terms differ by provider, particularly for platforms built on open-weights models, so compliance and procurement teams should review usage rights before deployment. There is also a legitimate concern about overreliance: automated narration works best as a complement to human-reviewed content, not a replacement for editorial oversight on materials where tone and accuracy carry real consequences.
Text to Speech has moved well past its origins as an accessibility feature. For organizations managing documentation, training, and customer communication at scale, it now functions as practical infrastructure, one that reduces production time and cost while opening multilingual reach that would otherwise require significant voice-talent budgets. As neural TTS models continue to close the gap with human narration, the decision point for most teams is no longer whether to adopt Text to Speech, but which platform delivers the naturalness, control, and pricing structure that fits their specific workflow.
Recommended reading: Learn How AI Software Supports Modern Workplace Communication
 Improve Document Workflows with Voice Automation
 How Voice AI Is Transforming Modern Clinical Documentation
 The Tech Revolutionizing AI Voice Bots and Customer Interactions
 How Voice Notes Are Transforming Modern Sales Strategies
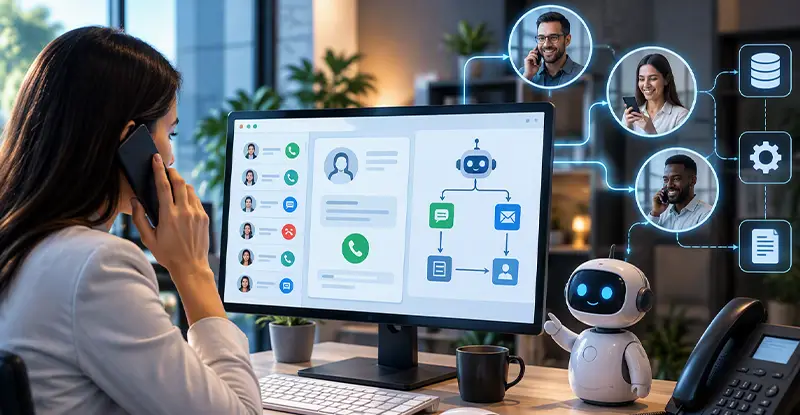 Automating Customer Communication: Virtual Numbers in Process Workflows
 AI-Generated Video: Transforming Corporate Training Programs

