How Advanced AI Models Are Expanding the Capabilities of Intelligent Document Processing
Published: September 25, 2026
Document automation used to work only when documents behaved themselves. Templates expected fields in fixed positions, while rules assumed that invoices, contracts, and claim forms would keep familiar layouts. A minor redesign could send an otherwise reliable workflow back to manual review.
Advanced AI models have changed the input side of that equation. Instead of matching each page against a predefined pattern, a large language model (LLM) can interpret language, layout, and visual context together. These frontier models bring document processing closer to reading than template matching.
That shift creates possibilities that older systems could not support, but it also introduces less predictable failure modes. The important question is no longer whether models can process unfamiliar documents. Instead, it is what specific work they can perform reliably and where their apparent understanding starts to break down.
Advanced AI can understand documents beyond fixed templates, but business value comes from turning that understanding into reliable processes. docAlpha combines AI-powered document capture, classification, extraction, validation, intelligent rules, and workflow automation.
Process more document types with less manual intervention while keeping people involved where judgment matters.
An invoice no longer needs the vendor name in the upper-left corner or the total in a predefined box. With multimodal capabilities, a model can identify the vendor, amount due, and payment terms from an unfamiliar layout by interpreting labels, surrounding text, and page structure.
Reasoning models also accept instructions that go beyond mapped fields. In a contract, the pipeline can flag language that shortens a notice period, connect that language to a termination clause, and return the relevant passage rather than merely extracting every date.
Classification changes in the same way. A claim form can be routed according to the type of loss described in its content, while a packing slip can be matched to a receiving workflow even when its filename is a random scan identifier. Understanding the AI and machine learning differences helps explain this shift: the system is interpreting a new input rather than matching it against one learned layout.
For an invoice workflow, the trade-off is flexibility versus predictable control. A rule-based system fails when a required coordinate is empty, making the cause visible. A generative model might instead infer a plausible total from nearby line items. That makes factual accuracy a testing requirement for each field, document type, and exception path.
Recommended reading: Learn How AI and Machine Learning Differ in Document Processing
No single model leads every document workload. Teams comparing GPT-5.4, Claude Opus 4.6, and Gemini 3.1 Pro on the same files either connect directly to each provider’s API, route requests through a multi-model endpoint like ZenMux, or self-host open-weight models behind their own firewall; the right route follows the documents and deployment constraints.
OpenAI’s GPT-5.4 and Anthropic’s Claude Opus 4.6 are practical picks for clause-level analysis across long contracts. These models can follow definitions, exceptions, and cross-references across dozens of pages, which matters when a limitation in one section changes the meaning of an obligation elsewhere.
They fit work such as comparing indemnity language against a playbook or tracing renewal conditions across an agreement. However, their higher processing demands make them less economical for reading a date from every routine invoice.
Google Gemini 3.1 Pro fits intake where documents combine photographs, handwriting, tables, stamps, and typed text without a clean text layer. Its multimodal capabilities allow one model to interpret visible page structure and language rather than relying entirely on OCR output.
That makes it relevant to photographed claim forms, annotated inspection reports, and scanned applications. However, deep learning techniques do not remove problems caused by poor source quality. Faint handwriting, cropped edges, and overlapping marks still require image-quality checks and targeted review.
Meta Llama and Mistral AI models trade some frontier-level accuracy for deployment control, predictable throughput, and better latency and cost efficiency at high volume. Self-hosting also keeps document content inside infrastructure controlled by the organization.
Small language models handle narrower jobs, such as finding dates, totals, and document types, without incurring frontier-model costs for every page. Most production pipelines therefore use tiers: a smaller model classifies and routes routine files, while a more capable model receives only contracts, exceptions, or ambiguous fields requiring judgment.
Reviewing every extracted field manually eliminates much of the value of intelligent automation. InvoiceAction automates routine invoice capture, validation, and matching while directing exceptions to employees for review.
Increase AP productivity while keeping human attention focused where errors or discrepancies carry greater consequences.
A large context window or token limit determines how much content a model can receive, not how reliably it recalls every detail. During long-document analysis, a model can identify the opening definitions and final signature terms of a 300-page contract yet miss a qualification buried near the middle.
Output ceilings create another constraint. Reading a long claim file may fit within the input allowance, but producing a structured record for every page can exceed the permitted response length. The pipeline then needs staged extraction, schema-specific batches, or an external store for intermediate results.
Chunking solves capacity problems while creating context problems. If a lease is divided by section, one chunk might contain an obligation, while another contains the definition that narrows it. Reasoning models need overlapping passages, retrieved cross-references, or a second synthesis pass to preserve that relationship.
Agentic AI extends the workflow beyond extraction. An agentic setup can read an invoice, retrieve its purchase order, compare quantities and prices, and send only mismatches to a human queue instead of stopping at a JSON payload.
Each additional step, however, creates another failure point. A mistaken vendor ID can retrieve the wrong purchase order, which then produces a convincing but irrelevant exception. Checks must therefore sit at each handoff, covering identity matching, retrieval, comparison, and final routing rather than treating the chain as one trusted decision.
Recommended reading: Discover How AI Algorithms Transform Intelligent Process Automation
A document pipeline must pass two separate gates. Accuracy determines whether extracted data can support a payment, claim, or contract decision. Governance and compliance determine whether the model can receive that document, where processing occurs, and what records the workflow keeps.
Hallucination in document processing often looks specific enough to escape casual review. A model might fill an absent effective date from nearby language or calculate a total from line items even though the page never states one. A low document-level hallucination rate can still hide unacceptable errors in payment amounts.
Generative confidence scores are not calibrated like template-matching scores. Thresholds need rebuilding against a labeled sample of the organization’s own invoices, contracts, or claims. SWE-bench and GPQA results say little about field-level factual accuracy because they test different abilities.
Human-in-the-loop review should target high-value fields, unsupported inferences, and low-confidence outputs. Reviewing every extracted vendor address and invoice total removes most of the economic benefit of automation.
Traditional capture struggles when layouts, formats, and document structures change. docAlpha uses intelligent document processing to understand and extract information from varied business documents, validate the results, and move accurate data into downstream workflows.
Reduce configuration and manual processing while building more flexible document automation.
Regulated documents can narrow the deployment choice before model quality enters the discussion. Data privacy and data sovereignty requirements may point toward self-hosted open-weight models, regional processing, or contracts that prohibit providers from training on submitted content.
Privacy reviews must cover more than the source document. Prompts, extracted fields, logs, cached responses, and evaluation samples all represent data movement or retention. NIST's Generative AI Profile provides a framework for incorporating trustworthiness and risk controls throughout system design, evaluation, and use.
Governance controls should follow the full workflow. Access permissions, retention periods, model versions, prompt changes, and reviewer decisions need traceability, particularly when the output supports a regulated or financially significant decision. Frontier models do not remove those obligations; they add new processing layers that governance must cover.
The capability question is largely settled. Frontier models can process unfamiliar layouts, interpret document language, connect information across pages, and pass extracted findings into downstream workflows. Template-based automation could not handle that range without extensive configuration.
The unresolved questions concern fit and verification. Contract reasoning, handwritten intake, repetitive invoice extraction, and regulated records do not call for the same model or deployment pattern. Workload complexity, document condition, latency, cost, and regulatory exposure matter more than leaderboard position. The strongest pipeline is therefore the one that assigns each document to an appropriate model and keeps human judgment exactly where an undetected error would carry real consequences.
Recommended reading: Learn How Human Oversight Strengthens Automated Document Processing
 Machine Learning vs AI – Comparing Two Revolutionary Technologies
 AI Algorithms in Intelligent Process Automation (2026 Guide) | Artsyl
 Automated Invoice Processing in 2025–2026: AI Automation with Human Oversight
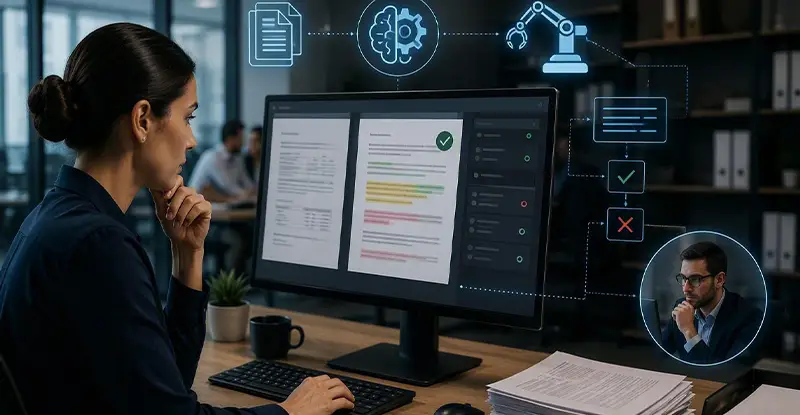 Human-in-the-Loop AI for Intelligent Document Automation
 All About Intelligent Document Processing
 Cognitive Capture: How AI Goes Beyond Traditional OCR

