Automating the SBA 7(a) Loan File: Where Document Processing Fits in Small Business Lending
Published: October 01, 2026
An SBA 7(a) loan is one of the most document-heavy products in small business finance. A single application can include several years of business and personal tax returns, interim financial statements, a debt schedule, ownership records, a business plan or projections, purchase agreements, appraisals, and a set of SBA forms that each carry their own signature and disclosure rules. Lenders, borrowers, and the intermediaries who sit between them all spend a large share of their time collecting, reading, re-keying, and checking these documents.
That makes the 7(a) program a useful case study for document automation in FinTech. The documents are standardized enough to automate, varied enough that simple templates fail, and regulated enough that errors carry consequences. This article walks through where the manual work sits in a typical 7(a) file, how intelligent document processing and workflow automation address it, and why fee disclosure has become one of the more important data points to get right.
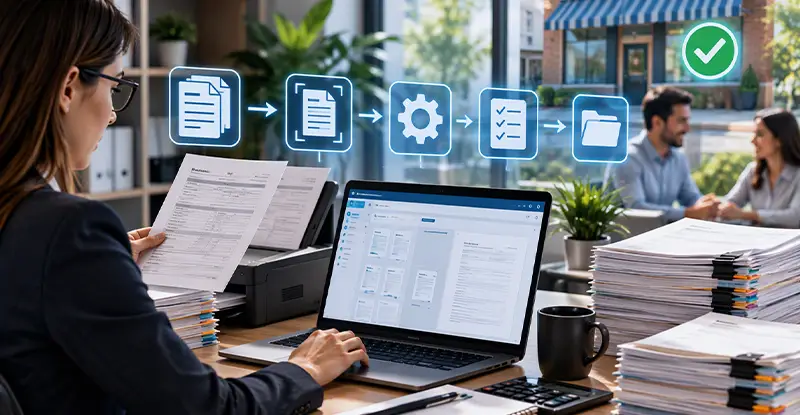
Loan processing slows down when employees have to identify documents, re-key financial information, check fields across multiple records, and track missing information manually. docAlpha combines intelligent document capture, classification, extraction, validation, and workflow automation to streamline document-intensive processes.
Spend less time processing paperwork and move complete, accurate information through lending operations faster.
It helps to group the documents by what the lender does with them.
Financial documents are used for underwriting. These include business tax returns, personal tax returns for each owner above the ownership threshold, year-to-date profit and loss statements, balance sheets, and accounts receivable and accounts payable aging reports. The lender extracts figures from these documents and "spreads" them, which means entering them into a standard analysis model to calculate cash flow and debt service coverage.
Identity and ownership documents confirm who the borrower is and who owns it: articles of organization, operating agreements, ownership breakdowns, and government-issued identification for principals.
Transaction documents describe the use of proceeds, such as a business purchase agreement, a real estate contract, equipment quotes, or a lease.
SBA forms and disclosures record program-specific information. These include the borrower information form and, when a third party is paid in connection with the loan, the SBA Form 159 Fee Disclosure and Compensation Agreement, which identifies each agent and what that agent was paid.
A typical file might contain 40 to 100 separate documents, arriving over several weeks, in formats ranging from clean accounting software exports to phone photos of signed pages.
Recommended reading: Discover How Document Processing Automation Supports the Banking Industry
Three stages absorb most of the manual effort.
Before anyone can underwrite, someone has to confirm that every required document has arrived, is the right version, covers the right period, and is signed where it needs to be. This is often tracked in a spreadsheet or email thread. Missing pages, unsigned forms, and outdated financial statements are the most common reasons files stall.
Analysts type revenue, cost of goods sold, officer compensation, depreciation, interest, and dozens of other line items from tax returns into the spreading model. For a business with multiple owners and affiliated entities, this can mean re-keying figures from ten or more returns. It is slow work, and a single transposed digit can change a debt service coverage calculation.
Figures that appear in several places need to agree. Revenue on the tax return should reconcile with the financial statements. Ownership percentages on the borrower forms should match the operating agreement. Fees shown on the disclosure form should match the closing statement. Checking these by hand requires someone to hold many documents open at once and compare them line by line.
Intelligent document processing combines document capture, optical character recognition, and machine learning models that recognize document types and extract specific fields. In a lending context, it replaces much of the re-keying and checking described above.
When a borrower uploads a batch of files, the system identifies each one: this is a 2024 business tax return, this is a year-to-date balance sheet, this is a signed fee disclosure form. It then compares what arrived against the required document list for that loan type and flags what is missing. The borrower gets a specific request for the missing items instead of a generic reminder.
Tax returns follow standard IRS layouts, which makes them good candidates for automated data capture. Extraction models pull line items directly into the spreading template, with confidence scores for each field. Analysts review low-confidence values and exceptions instead of typing every number. Financial statements vary more by format, but machine learning models trained on common accounting software exports handle most of them with limited review.
Underwriting depends on accurate information, but much of that data begins inside tax returns, financial statements, applications, and supporting documents. docAlpha captures and validates information from varied document formats while directing low-confidence values and exceptions to the appropriate users.
Reduce repetitive data entry and give lending teams faster access to the information they need for informed decisions.
Once data is structured, rules can check it across documents automatically. The system can compare revenue across the tax return and the income statement, confirm that ownership percentages add up to 100 percent and match the governing documents, and verify that the compensation on the fee disclosure form matches the amounts on the settlement statement. Differences above a set tolerance are routed to a person with the specific documents and fields highlighted.
Of all the fields in a 7(a) file, agent compensation has drawn the most regulatory interest in recent years. SBA rules require the fee disclosure form whenever an agent is paid by either the applicant or the lender in connection with the loan. The form has separate lines for amounts paid by the applicant and amounts paid by the lender, and it is signed by the applicant, the agent, and the lender. It is a disclosure inside a specific loan file, not a license or a credential.
Congress has also shown interest in this data. The 7(a) Loan Agent Oversight Act, introduced as H.R. 1804, would require the SBA to report annually on agent activity, including how many agents assist applicants, purchase rates on agent-assisted loans, and the number and total value of referral fees paid to agents. Whatever happens with that bill, the direction is clear: agent compensation is being treated as reportable data.
For lenders, that means fee disclosure information should not live only on a signed PDF. When document processing tools extract the agent name, agent type, applicant-paid amount, and lender-paid amount from each form, that information can feed a portfolio-level report. Compliance teams can see total agent compensation by channel, identify files where the disclosure is missing or does not match the closing documents, and answer regulator or auditor questions without pulling individual files.
Recommended reading: Learn How AI Extracts Structured Data From Financial Documents
Many 7(a) applications reach a lender through an intermediary rather than directly from the borrower. Brokers and packagers collect documents, organize the file, and route it to lenders likely to approve that type of loan. From a document processing standpoint, a well-prepared file from an intermediary is a cleaner input: documents arrive complete, labeled, and in consistent formats.
The compensation structure matters for the data as well. An SBA 7(a) loan broker that works on a lender-paid basis, where the borrower pays nothing and the lender pays the broker when the loan funds, still has to appear on the fee disclosure form, because the form covers lender-paid compensation as well as borrower-paid fees. When that arrangement is captured as structured data, lenders can track which referral channels produce complete files, how long those files take to close, and how they perform after funding.
That kind of channel-level business intelligence is difficult to produce when agent information sits only in scanned signatures. It becomes routine once the disclosure data is extracted and stored alongside the rest of the loan record.
Important lending and compliance information should not remain trapped inside PDFs, scanned forms, and document folders. docAlpha extracts and validates document data so it can support downstream workflows, reporting, and business processes.
Create a stronger information foundation for underwriting, compliance, audit response, and portfolio reporting.
Lenders considering automation for their 7(a) operations can approach it in stages rather than as one large project.
Start with intake classification and completeness checks, because missing documents cause more delay than any other single issue. Next, automate data capture from tax returns, which are the most standardized financial documents in the file and the most time-consuming to re-key. Then add cross-document consistency rules, beginning with the checks that most often surface problems: revenue reconciliation, ownership totals, and fee disclosure amounts. Finally, connect the extracted data to reporting, so compliance and portfolio management can work from structured records instead of document folders.
Each stage reduces manual data entry and shortens time to decision on its own. Together, they turn the loan file from a stack of documents into a dataset, which is where small business lending is heading as reporting expectations grow and borrowers expect faster answers.
 AI and OCR: Faster, Smarter Online Loan Processing
 Loan Approval Workflows
 Document and Workflow Automation for Mortgage Risk Control
 Accelerating Financial Approvals with AI-Powered Automation
 Data Extraction with OCR: Extracting Data from Invoices, Forms, Receipts
 Best Fintech OCR Automation Platforms and Partners in 2026

