Why Every Pasted PDF Table Needs Text to Columns in Excel
Published: September 24, 2026
You copy a table out of a PDF, paste it into Excel, and every row lands in column A as one long string. The numbers are all there. The columns are gone. It looks like a paste error, but the real cause sits inside the PDF itself, not in anything you did wrong, and retyping the whole sheet by hand shouldn't be the only way out.
A PDF has no concept of rows and cells the way Excel does. Under the hood, it only stores instructions for drawing characters at specific positions on a page. A table's neat columns are really just text placed at consistent horizontal spacing, nothing more. No boundary marks where one column ends and the next begins, and no row identifier ties a number back to the label next to it.
Copy that text, and the visual alignment doesn't travel with it. Excel receives a string of characters and line breaks, with no delimiter telling it where to split a column. Everything from one row lands in a single cell, in whatever order the PDF happened to store it. A small number of PDFs include hidden structure tags meant for screen readers, but most business documents and scanned reports skip that step entirely, leaving nothing for Excel to latch onto.
Rows, columns, and relationships that look obvious to a person can disappear when PDF content is copied into another application. docAlpha uses intelligent document processing to understand and extract information from complex documents and tables.
Reduce manual cleanup and move accurate, structured data directly into downstream business processes.
The damage usually shows up in a few specific ways. Column headers can blend into the first row of tabular data instead of sitting above it. Numbers can pick up stray formatting characters that make Excel treat a real value as plain text instead of something it can add up. Rows can even land out of order, since a PDF often stores each column as a separate block of text rather than one row at a time.
None of this is random. It follows directly from a PDF's habit of tracking where characters sit, not what those characters mean. Any data extraction method that relies on the pasted text alone inherits the same blind spot, no matter how carefully the paste itself is done.
A period used as a thousands separator in the source file is a common trip-up too, since Excel can read it as a decimal point instead and quietly change the value of every number that carries one.
Recommended reading: Learn How OCR Extracts Usable Data From Business Documents
Turning to Text to Columns in Excel is usually the first thing people try. Under Data, the wizard takes one pasted column and splits it using a delimiter you choose, like a comma or a tab, or a fixed width based on character position.
It works cleanly on simple, consistent data. Real pasted tables rarely stay that cooperative:
- Column widths shift slightly from row to row in the source PDF
- A single value with an internal space can get split into two columns by mistake
- Merged or wrapped cells in the original table throw off every row after them
One misaligned row is usually enough to send the rest of the sheet out of sync, and fixing it by hand defeats the purpose of pasting in the first place.
Two workarounds get mentioned a lot. Pasting into Word first sometimes preserves more structure, though you still need to fix the mess by hand in Excel afterward. Microsoft 365's Power Query can pull a table straight from a PDF, but it can't read a scanned page and tends to import the whole file instead of just the one table you need.
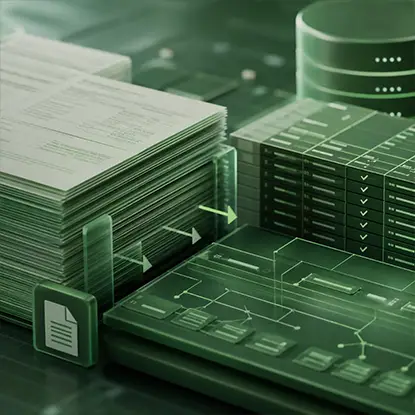
A PDF preserves how information looks on a page, not necessarily the rows, columns, and relationships your downstream systems need. docAlpha captures document content and transforms it into structured, validated business data.
Move beyond visual documents and make extracted information ready for automation.
Software built specifically to handle PDF to Excel conversion looks at the table the way a person would, reading column boundaries and row breaks directly off the page instead of working from one flat block of text. That's the gap between software built to extract tables from PDF files and a plain copy-paste, which never had that context. The same approach works on a scanned report too, something copy-paste or Text to Columns can't recover on its own.
For a table you need in working order without any manual splitting, convert PDF to Excel for free with OnlyDoc, which rebuilds the original columns directly instead of dumping everything into one. The numbers land as real values too, so they plug straight into a new formula instead of sitting there as unusable text. It currently handles one file at a time, which covers most everyday cases without any extra setup.
Recommended reading: How to Use OCR Software for PDFs and Other File Formats
A PDF was never built to hold a real table, so the columns were never going to survive a plain copy-and-paste. Rebuilding them by hand with Text to Columns works for simple cases, and converting the file directly skips that step entirely. Either way, the fix starts with knowing why the column disappeared in the first place.
 PDF OCR Conversion
 Data Extraction with OCR: Extracting Data from Invoices, Forms, Receipts
 Discover Everything You Need to Know About Data Extraction
 Best PDF Conversion Formats for Accuracy & Quality
 OCR Image to Text Conversion: What is It?
 Cognitive Capture: How AI Goes Beyond Traditional OCR

